How to Track Your Brand's Visibility in AI Search Results
AI Search Visibility Tracking is a measurement task, not a campaign promise. Seeing your business named once in an assistant answer gives you an observation. It does not establish how often customers encounter the brand, whether the description is correct, or whether the answer produces a visit. A useful monitoring process keeps those questions separate.
AI Search Visibility Tracking is a measurement task, not a campaign promise. Seeing your business named once in an assistant answer gives you an observation. It does not establish how often customers encounter the brand, whether the description is correct, or whether the answer produces a visit. A useful monitoring process keeps those questions separate.
Build a small, repeatable panel of customer questions, preserve the answers and citations, and compare equivalent runs over time. This article focuses on the evidence sheet and review routine: what to record, how to interpret changes, and when a finding deserves action. It does not repeat a general guide to optimizing for AI search.
Define the outcomes you will count
A named mention, a recommendation, and a citation are different outcomes. A company might appear as a passing example without being recommended; a source link might support a fact without endorsing the publisher. Write a scoring guide before collecting answers. Record brand presence, recommendation status, citation destination, and factual accuracy as separate fields rather than collapsing them immediately into one score.
Specify the market, language, product and customer group under review. For a regional service provider, questions from outside the service area may be irrelevant. For software, an enterprise comparison differs from a beginner tutorial. Brand Visibility in AI Search should be described within that scope so stakeholders know which audience the observations plausibly represent.
Build a fixed customer-question panel
Collect questions from genuine sales conversations, support tickets, query reports and customer interviews. Include discovery, comparison and suitability questions alongside branded queries. Someone asking whether your product supports a task already knows its name; someone asking which tools suit that task may not. Label these intentions separately so branded recall does not masquerade as discovery.
Maintain a fixed core panel and a separate exploratory list. Save the exact prompt wording and an identifier. Do not quietly replace an unsuccessful prompt with a friendlier one next month. Retire irrelevant questions with a dated note. Choose a sample your team can actually repeat; methodological consistency matters more than an impressive prompt count.
Record the conditions of every run
For each answer, save the date, platform, visible model or mode, language, location context where available, and whether the session has personalization or prior conversation history. A fresh conversation can reduce some contextual differences, but it does not make the system deterministic. Record unavailable settings as unknown rather than inventing control over them.
Keep runs from unlike surfaces distinct. A browsing-enabled answer and a non-browsing response are not equivalent measurements. If a platform changes its interface or product behavior, annotate the change before interpreting a trend. Repeated runs can reveal variability; preserve all valid observations instead of selecting whichever answer contains the most favorable ChatGPT Brand Mentions.
Create an auditable evidence sheet
Use columns for prompt ID, run conditions, answer excerpt, brand mention, recommendation, cited URLs, factual errors, and an evidence reference. Save a permitted screenshot or answer record where company policy allows. Protect personal information: customer questions should be generalized before being entered into an external service or shared in a reporting folder.
AI Citation Tracking should capture the exact page, not just the domain. Check whether the linked page supports the claim next to it and whether the destination remains accessible. Distinguish a visible citation from an unlinked mention. A reviewer should be able to reconstruct the observation without relying on the original operator's memory or enthusiasm.
Report denominators and uncertainty
Describe counts as results for a defined panel and period. A report might say the brand was named in eight of twenty recorded runs; that is an illustrative reporting format, not CSSHouse performance data. Calling that result a universal visibility percentage would overstate what was measured. State missing runs, interface errors and non-comparable conditions separately.
Do not infer market share, customer reach or causal impact from a small sample. Prompt selection, answer variability and product updates can affect the observations. Compare sustained patterns across equivalent runs, then investigate plausible explanations. If you combine platforms into a summary, document weighting and keep the underlying results available so a convenient score does not conceal contradictory evidence.
Keep referrals separate from answer visibility
An answer can mention a brand without generating a click. A visitor can also arrive later by typing the name, using another device, or following a recommendation outside the sampled prompts. Review identifiable AI-related referral sources and landing pages in analytics, but label the reporting limitations. Missing referral information does not prove that AI exposure never occurred.
Maintain stable channel definitions and verify conversion events. Add campaign parameters only to links you control; you cannot generally attach them to citations generated by an external assistant. A CRM discovery question can supplement click data, but customer recall is imperfect. Keep observed mentions, measurable referrals and self-reported influence in separate columns before discussing their relationship.
Turn observations into proportionate actions
Prioritize factual errors that could mislead customers, such as incorrect service coverage or an obsolete product description. Find the source of the conflicting information before changing unrelated pages. Verify your own official pages, then review the cited profile or publisher. A correction request needs evidence, an owner and a follow-up date, not a demand that an assistant favor the brand.
Where the problem is missing information, identify the exact customer question your website fails to answer. Improve that material only when it benefits visitors and can be supported by facts. Re-run affected prompts afterward, recording a follow-up observation rather than claiming the edit caused a citation. Other sources and system changes may have contributed.
Run a sustainable AI search monitoring review
Assign an operator, a reviewer and a cadence that fits the business. A stable brand may begin with a monthly panel; a major product change could justify an additional check. Publish a short report containing scope, observations, uncertainty, referral context and outstanding corrections. The cadence is a planning recommendation, not a universal standard.
Audit the process itself periodically. Are the questions still representative? Are evidence records readable? Are scoring decisions consistent between reviewers? Discuss ambiguous answers together and update the scoring guide transparently. AI Search Monitoring becomes useful when it creates a reliable decision trail, rather than a collection of screenshots celebrating whichever response looked most impressive.
Choose your next practical step
Need help with your digital growth? Let's talk about your project.
Discuss your projectKey takeaways
- Define the outcomes you will count
- Build a fixed customer-question panel
- Record the conditions of every run
- Create an auditable evidence sheet
Frequently asked questions
No. A prompt panel observes a selected set of questions and conditions. Most tools cannot provide a complete census of private conversations. Report the boundaries of the sample and avoid describing its counts as total customer exposure.
Conclusion
AI Search Visibility Tracking is most credible when the sample, scoring and evidence remain inspectable. Keep mentions, citations, accuracy and referrals distinct; report denominators and unknowns. Use the findings to correct real information problems and answer genuine customer questions, without promising universal visibility or attributing every change to your latest edit.
Want this done for you?
Book a free strategy call and we will review your site, your search visibility and your ad accounts, then tell you the three highest-impact things to fix first.
About the author
Gurpreet leads strategy and delivery at CSSHouse Consulting, where he has spent the last decade building websites and search programs for service businesses, SaaS teams and ecommerce brands across India, the UK and North America.
Work with our teamRelated articles
Entity SEO: How to Build Your Brand's Authority Across Search Engines
Entity SEO starts with a practical question: can a customer or search system determine which organization your website represents? Similar names, old addresses, conflicting profiles and unclear relationships between products and companies can create confusion. Adding markup to an inconsistent identity does not fix the underlying facts.
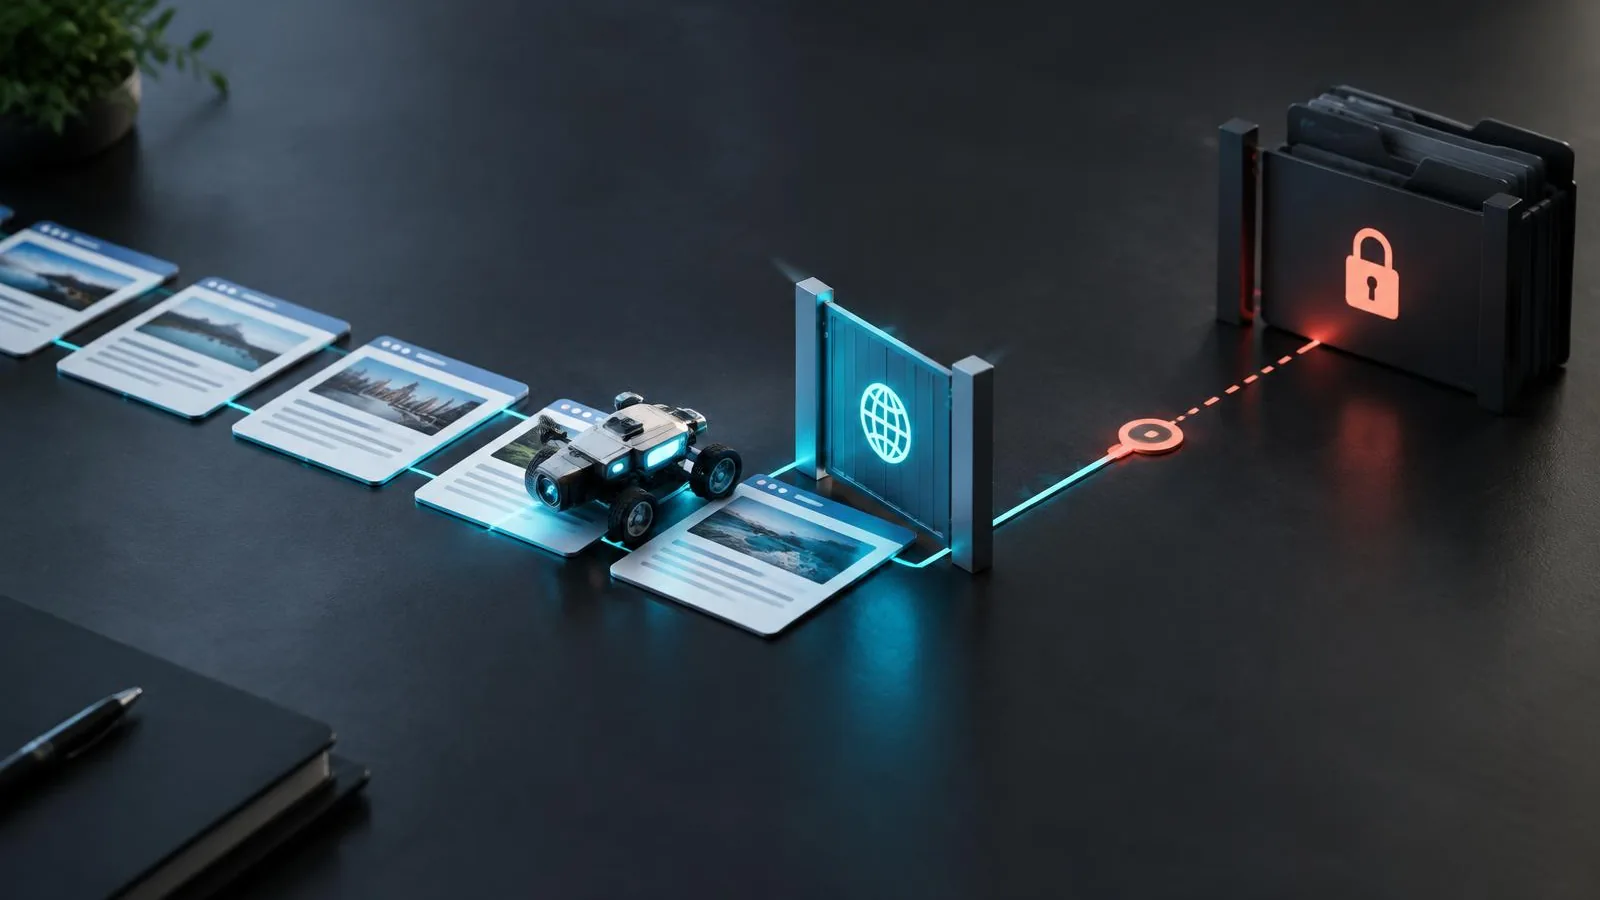
Technical SEO for AI Search: Is Your Website Ready for AI Crawlers?
Technical SEO for AI Search is an access and interpretation audit. A page that looks complete to a signed-in visitor can return a challenge, an empty shell or an error to an automated request. Before discussing citation outcomes, establish whether the intended public content is reliably available and whether the relevant agent is permitted to request it.
AI SEO vs Traditional SEO: Which One Actually Works in 2026?
AI SEO and traditional SEO solve different parts of the search puzzle, and in 2026 you need both working together.