Technical SEO for AI Search: Is Your Website Ready for AI Crawlers?
Technical SEO for AI Search is an access and interpretation audit. A page that looks complete to a signed-in visitor can return a challenge, an empty shell or an error to an automated request. Before discussing citation outcomes, establish whether the intended public content is reliably available and whether the relevant agent is permitted to request it.
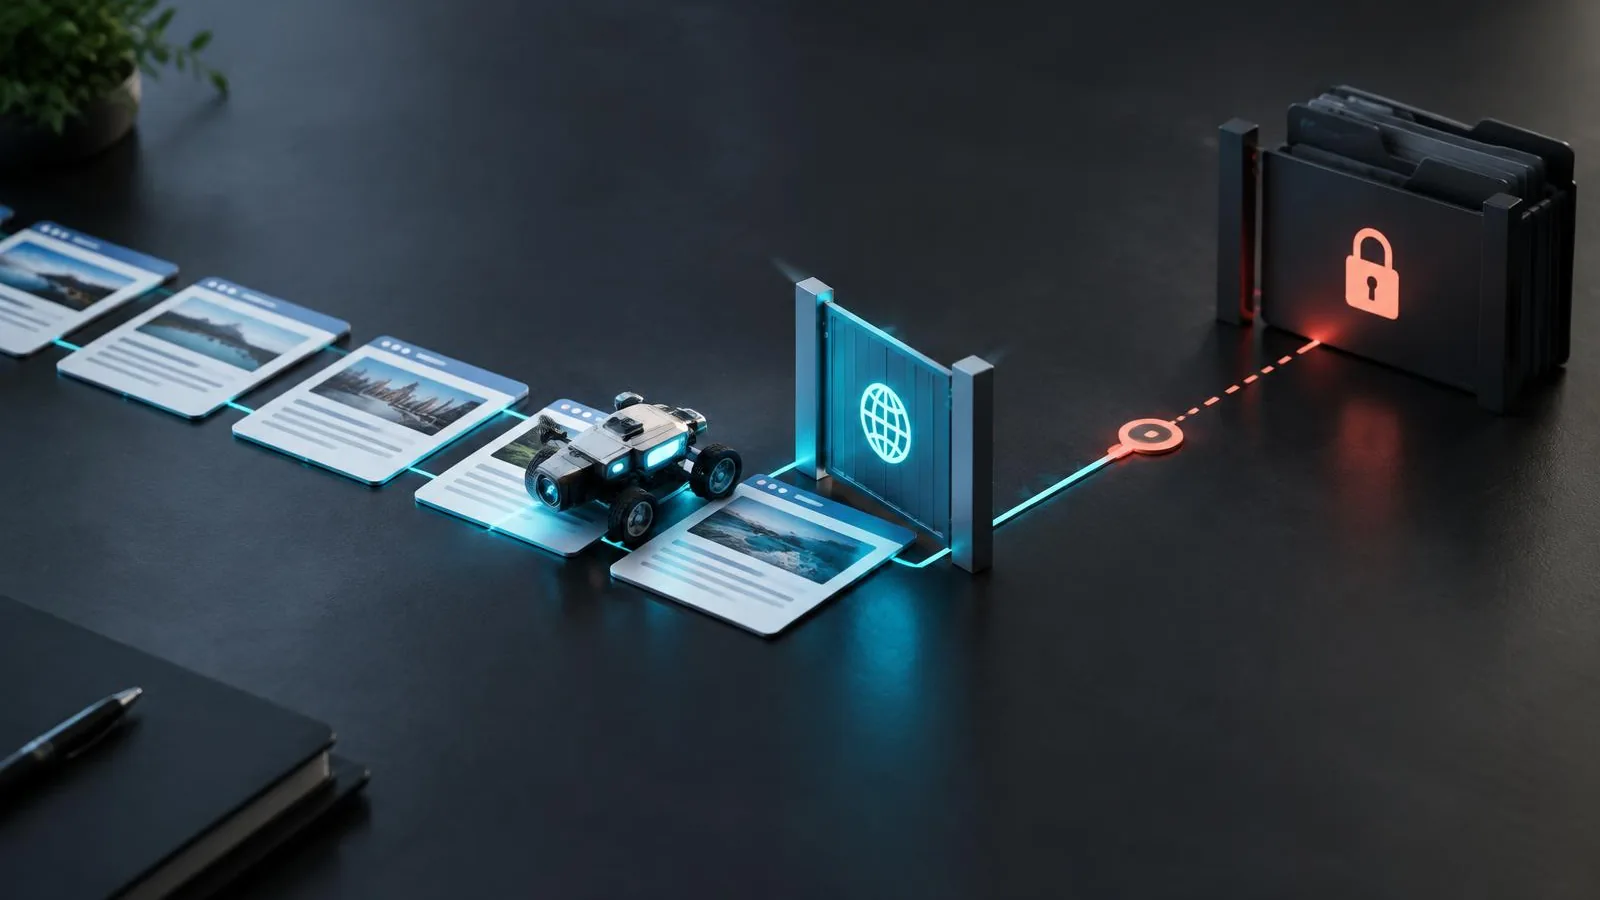
Technical SEO for AI Search is an access and interpretation audit. A page that looks complete to a signed-in visitor can return a challenge, an empty shell or an error to an automated request. Before discussing citation outcomes, establish whether the intended public content is reliably available and whether the relevant agent is permitted to request it.
Different AI Crawlers have different purposes. Search discovery, model-training collection and user-triggered fetching are not interchangeable. This guide concentrates on identifying those purposes, testing actual responses and tracing failures through infrastructure. Permission to crawl does not guarantee indexing or a mention, and crawler instructions are never a substitute for protecting private data.
Create a purpose-based crawler inventory
List each operator, its documented user agents, the stated purpose and your organization's access decision. Consult current official documentation because names and behaviors change. An operator may provide different agents for search, training and user-initiated browsing. A blanket rule for one company name can conceal distinctions your content, legal or security teams consider important.
Record the documentation review date and policy owner. Decide separately whether public pages may be discovered for search and whether content may be collected for other uses. Consider rights, service expectations and infrastructure capacity. This is an organizational decision, not a universal SEO recommendation. Do not copy a bot list from an old article and assume it still controls the intended service.
Test representative public HTTP responses
Select examples from each important page type: homepage, service page, article, product and a page with substantial client-side behavior. Fetch them without a logged-in session and record the final status, redirect chain, content type and response body. Repeat suspicious results to distinguish a persistent condition from an isolated incident. Browser availability is useful evidence but only one perspective.
Look for unexpected 403 denials, 429 rate limits and server errors. Check whether redirects lead to the intended hostname and path, and whether the destination agrees with canonical tags. Avoid disabling security controls simply because a test request failed. Identify which layer produced the response and whether the requester should legitimately have access before adjusting a rule.
Review robots and indexing instructions independently
Read the live robots.txt on each relevant hostname. Evaluate user-agent groups and matching paths using the operator's documented behavior. A rule on the main domain does not automatically apply to a subdomain. Keep test cases for important allowed and excluded paths so a broad change cannot silently reverse the intended policy.
Inspect robots meta and X-Robots-Tag headers separately. For conventional search engines, a crawler usually needs access to read a page's noindex instruction; blocking the fetch can prevent that discovery. Robots.txt requests compliant crawler behavior, but it is not authentication and does not reliably hide a public URL. Enforce private access through server-side authentication and authorization.
Inspect CDN and firewall decisions
A content delivery network or web application firewall can challenge bots, block regions or impose rate limits before the application receives a request. Compare the observed response with the infrastructure's event records. Capture rule identifier, action and affected resource pattern. A successful request from one location does not establish that all permitted automated clients receive the same content.
Verify legitimate crawler identity using the operator's current guidance where available. User-agent text alone can be spoofed. Use documented network checks rather than trusting any request that announces a familiar bot name. Tune access narrowly when justified, retain protection for abusive traffic and monitor resource usage after a change. Technical AI SEO should improve dependable public delivery without creating a security exception for strangers.
Compare initial HTML and rendered text
Check whether headings, essential copy, navigation and meaningful links exist in the initial response or become available reliably through rendering. A client-side application may rely on scripts and API calls that fail for an unauthenticated request. Not every agent executes JavaScript in the same way. Test the actual representation rather than assuming browser screenshots describe what a crawler receives.
Review required script, style and image requests as well as the document. Essential information should not require a fragile interaction, account session or inaccessible embedded frame. Prefer robust delivery and progressive enhancement for public content. This does not mean JavaScript is forbidden; it means Website Crawlability depends on implementation, resource access and the capabilities of the specific service under review.
Use request logs as evidence, not ranking proof
Server and CDN logs can show which paths were requested, when and how delivery responded. Under an appropriate retention and access policy, examine status, latency, response size and cache or firewall outcome. Look for repeated errors affecting important page patterns. Minimize personal data and avoid sharing raw logs publicly when they contain sensitive request information.
Correlate failures with releases, infrastructure updates and incidents. A request arriving after a site change does not prove that the change attracted a crawler. Likewise, a successful fetch does not establish indexing, understanding or citation. Logs answer delivery questions; use separate tools or observations for index status and answer visibility. Document these boundaries in the audit report.
Validate structured data against visible facts
Structured Data for AI Search should follow the same accuracy discipline as other markup. Choose documented types that fit the page, validate syntax and supported properties, and ensure the values match visible information. Review stale prices, organization facts or publication details when content changes. Adding elaborate markup that describes something the page does not show is not a legitimate visibility tactic.
There is no general special schema that guarantees an AI recommendation. Structured data can provide explicit context and support eligible search features, but it cannot compensate for missing copy or denied access. Keep entity identity checks separate from delivery checks: valid markup and a successful HTTP response solve different problems and neither alone proves an answer will cite the page.
Retest the failure and its sibling paths
Create an issue register with page pattern, evidence, responsible layer, severity, owner and expected result. If a firewall rule blocks one article, test other articles sharing the pattern. If rendering misses product text, check other pages using the same template. Fix the category of failure rather than accepting success on one conveniently chosen URL.
After a change, repeat the original request and examine fresh evidence. Confirm that private pages remain protected, public pages still follow intended indexing instructions and resource usage remains acceptable. Add a scheduled check after major hostname, rendering or infrastructure changes. A durable crawler audit leaves owners and test cases behind; it is not a one-time declaration that the website is ready forever.
Choose your next practical step
Need help with your digital growth? Let's talk about your project.
Discuss your projectKey takeaways
- Create a purpose-based crawler inventory
- Test representative public HTTP responses
- Review robots and indexing instructions independently
- Inspect CDN and firewall decisions
Frequently asked questions
No universal answer applies. Review each documented purpose alongside rights, privacy, infrastructure and business goals. Record the decision and test the relevant rules without treating broad access as a ranking guarantee.
Conclusion
Technical SEO for AI Search is a repeatable audit of purpose, permissions and delivery. Check responses, rendering, infrastructure and logs; retest the exact failure and related paths. Keep training preferences distinct from search discovery and private access controls. Report what the evidence proves: reliable public access, not a guaranteed place in an AI answer.
Want this done for you?
Book a free strategy call and we will review your site, your search visibility and your ad accounts, then tell you the three highest-impact things to fix first.
About the author
Gurpreet leads strategy and delivery at CSSHouse Consulting, where he has spent the last decade building websites and search programs for service businesses, SaaS teams and ecommerce brands across India, the UK and North America.
Work with our teamRelated articles
How to Track Your Brand's Visibility in AI Search Results
AI Search Visibility Tracking is a measurement task, not a campaign promise. Seeing your business named once in an assistant answer gives you an observation. It does not establish how often customers encounter the brand, whether the description is correct, or whether the answer produces a visit. A useful monitoring process keeps those questions separate.
Entity SEO: How to Build Your Brand's Authority Across Search Engines
Entity SEO starts with a practical question: can a customer or search system determine which organization your website represents? Similar names, old addresses, conflicting profiles and unclear relationships between products and companies can create confusion. Adding markup to an inconsistent identity does not fix the underlying facts.
AI SEO vs Traditional SEO: Which One Actually Works in 2026?
AI SEO and traditional SEO solve different parts of the search puzzle, and in 2026 you need both working together.